
8 Best Data Lake Tools in 2026, Compared
Compare the 8 best data lake tools on open table formats, query engines, governance and real consumption cost, with every price checked on vendor pages.
 Shamim Mia, Founder, SerpAstraLast verified November 6, 20269 min read
We compare pricing pages, documentation and public reviews. We never accept payment for rankings.
Key takeaways
- Databricks is the most complete lakehouse here, with Unity Catalog governance and a free edition; paid compute starts at $0.15 per DBU for Jobs Compute.
- Google BigQuery is the cheapest way to start: the first 1 TiB of queries and 10 GiB of storage are free every month.
- Microsoft Fabric is the only tool with a flat capacity price, from $262.80 a month for F2 pay-as-you-go, which suits Microsoft shops that want predictable bills.
- If the data cannot move, Starburst and Dremio query it where it already sits, and both have free plans.
On this page
Quick comparison
| Tool | Best for | Starting price | Free plan |
|---|---|---|---|
| Databricks | Teams that want one lakehouse for engineering, SQL analytics and machine learning on open formats | From $0.15/DBU | Yes (free plan) |
| Snowflake | SQL-first teams that want lake data and warehouse tables managed without infrastructure work | $2/credit | No (trial only) |
| Google BigQuery | Google Cloud teams that want a serverless lake and warehouse with a real free tier | Free tier; $6.25/TiB | Yes (free plan) |
| Amazon Redshift | AWS shops whose lake already sits in S3 and that want a fast warehouse on top | From $1.50/hr | No (trial only) |
| Microsoft Fabric | Microsoft shops that want OneLake, pipelines and Power BI on one capacity bill | $262.80/mo | Yes (free plan) |
| Starburst | Teams that need to query lake, warehouse and database data together without moving it | Free plan; usage-based | Yes (free plan) |
| Dremio | Teams building an open lakehouse on Apache Iceberg that want fast self-service SQL | Custom quote | Yes (free plan) |
| Cloudera | Regulated organisations that need one lake platform across on-premises and public cloud | Custom quote | No |
Make one of these tools?
We re-check this list every quarter. Send a correction, request a review, or ask about a clearly labeled sponsored spot.
Request a listingThe best data lake tools
Databricks
Best for: Teams that want one lakehouse for engineering, SQL analytics and machine learning on open formats
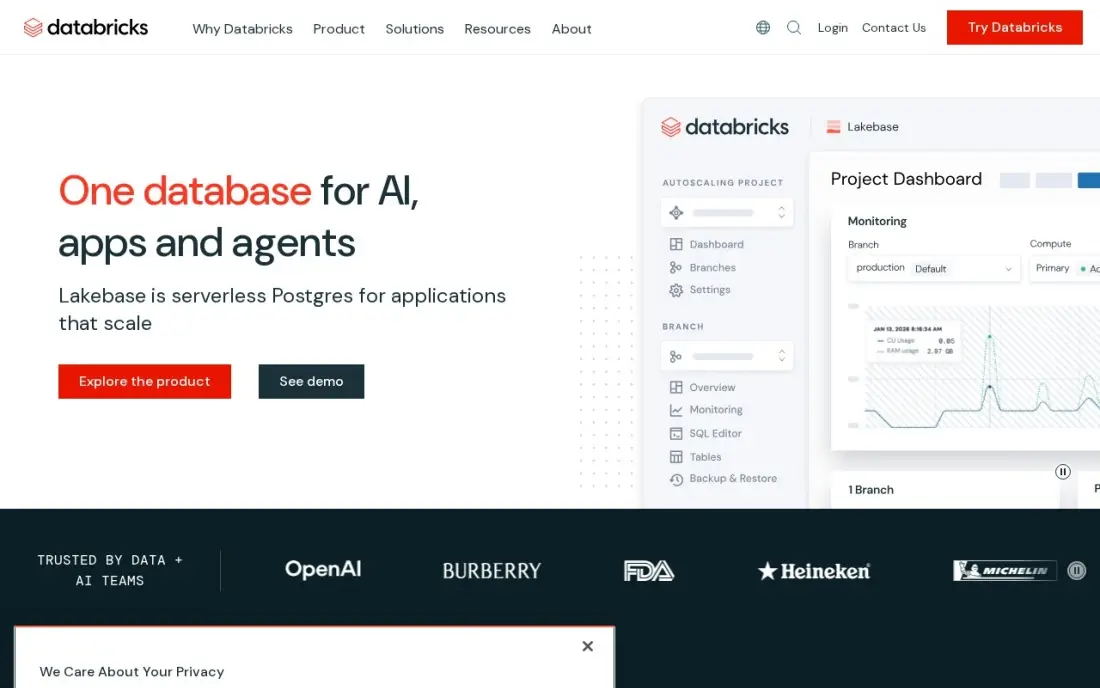
Databricks is the company that popularised the lakehouse, and it is still the fullest version of the idea. Raw files land in cloud object storage, Delta tables add transactions and versioning, Spark and SQL engines process them, and Unity Catalog governs tables, files and models in one place. Engineers, analysts and data scientists work on the same copy of the data.
The bill is consumption-based. Jobs Compute starts at $0.15 per DBU on the Premium tier in AWS US East, interactive compute costs more, and on classic compute the cloud servers are billed separately. A free edition covers learning and small experiments. Without someone watching cluster use, costs climb quickly.
What we like
- One platform for warehousing, engineering and machine learning on open formats, with Apache Spark underneath
- Unity Catalog governs data and AI assets in one place, from tables to models
- Serverless compute removes cluster management, and the ecosystem spans ingestion to BI
- Free Edition covers learning and small experiments at $0
Watch out for
- Consumption pricing needs active cost management, or bills climb fast
- Classic compute bills cloud infrastructure separately, on top of the DBU rate
- Rewards Spark and Python skills; pure SQL teams face a learning curve
Snowflake
Best for: SQL-first teams that want lake data and warehouse tables managed without infrastructure work
Snowflake is a cloud warehouse rather than a lake, but many teams run it as the governed SQL layer next to their lake storage. Storage and compute scale separately, warehouses start and stop in seconds, data sharing lets partners query live tables without copies, and analysts only need SQL.
Standard edition costs $2 per credit on demand in AWS US East, Enterprise $3 and Business Critical $4, with storage around $40 per TB a month. Needing one Enterprise feature reprices every credit. A 30-day trial includes $400 in credits. Choose Snowflake when ease of use matters more than engineering control.
What we like
- Storage and compute scale separately, and warehouses start and stop in seconds
- Data sharing lets partners query live tables without copying data
- Analysts write plain SQL while the platform handles all infrastructure
- Marketplace adds third-party datasets to the same queries
Watch out for
- Costs can surprise without governance: every credit burns at the edition rate
- Needing one Enterprise feature reprices every credit in the account to $3
- Streaming and machine learning are less central than on Databricks
Google BigQuery
Best for: Google Cloud teams that want a serverless lake and warehouse with a real free tier
BigQuery is serverless, so there are no clusters to size: you load or link data, write SQL and Google scales the engine. It scales from a single query to petabytes, BigQuery ML runs models in SQL, and Gemini helps write queries. For a team already on Google Cloud, it is the shortest path to a working lake.
On-demand queries cost $6.25 per TiB scanned, with the first 1 TiB of queries and 10 GiB of storage free every month, so small workloads often cost nothing. The risk is an unfiltered scan of a large table, which can burn the free tier in one query; partition tables and set query limits from day one.
What we like
- Fully serverless: no clusters to size, no servers to patch, automatic scaling
- Generous free tier: 1 TiB of queries and 10 GiB of storage free every month
- BigQuery ML brings machine learning to SQL users, with Gemini help for queries
- Deep Google Cloud integration, from Vertex AI to Looker Studio
Watch out for
- Query costs need monitoring: one unfiltered scan of a large table burns the free tier
- GCP-centric, so multi-cloud strategies get complicated
- Capacity editions add a second pricing model to learn
Amazon Redshift
Best for: AWS shops whose lake already sits in S3 and that want a fast warehouse on top
For data already in Amazon S3, Redshift is the natural engine: it queries S3 files directly without loading them first and plugs into Glue, Athena, SageMaker and QuickSight. Serverless mode scales with the query queue and stops billing when idle, so a small team does not have to size a cluster.
Serverless starts at $1.50 an hour for the 4-RPU minimum, at $0.375 per RPU-hour in US East, and a $300 trial credit lasts 90 days. Pricing has many parts — compute, managed storage, Spectrum and concurrency scaling — so model a month of real queries before you commit. Outside AWS, its advantages fade.
What we like
- Fast columnar engine that queries data in S3 directly, with no loading step
- Serverless mode scales with the query queue and pauses billing when idle
- Deep AWS integration: Glue, Athena, SageMaker and QuickSight in the same stack
- Reserved capacity and Serverless Reservations cut the on-demand rate
Watch out for
- Pricing is complex: RPU-hours, node-hours, storage and Spectrum all bill separately
- Best inside AWS; the value fades for teams on other clouds
- Concurrency scaling and Spectrum charges can push the bill past the estimate
Microsoft Fabric
Best for: Microsoft shops that want OneLake, pipelines and Power BI on one capacity bill
Fabric's lake is OneLake: one logical store for the whole organisation, which lakehouses, warehouses, notebooks, real-time analytics and Power BI all read without copying. Identity and governance come from the Microsoft tenant you already run, and Power BI reports read lake tables directly.
It is the only tool here with a flat capacity price. The smallest F2 capacity costs $262.80 a month pay-as-you-go in East US, or about $156.33 on a one-year reservation, with OneLake storage billed separately. Below F64, every report viewer still needs a Power BI Pro licence at $14 a month, and Copilot needs larger capacities.
What we like
- One capacity covers lakehouse, pipelines, notebooks, real-time analytics and Power BI
- OneLake means a dataset built once serves every workload, with no copies
- Fits Microsoft shops: same identity, same governance, Power BI reads the lake directly
- Capacity can be paused, and reservations cut the pay-as-you-go rate by about 40%
Watch out for
- Below F64 every report viewer still needs a Power BI Pro licence at $14 a month
- Copilot features need larger capacities, so the entry F2 misses the AI headline
- Consumption billing is hard to predict until real workloads have run for a month
Starburst
Best for: Teams that need to query lake, warehouse and database data together without moving it
Starburst Galaxy is a managed version of Trino, the open-source query engine, and it treats the data lake as one source among many. A single SQL query can join files in S3 with tables in Snowflake or an operational database, and the data stays under its existing governance rather than being copied into another store.
There is a free plan for exploring, and a 30-day Enterprise trial with $500 in credits. Paid pricing is pay-as-you-go and quote-led, with no published monthly rate. Starburst queries data but does not store or transform it, so pair it with object storage and a pipeline tool.
What we like
- Queries data where it lives — lakes, warehouses and operational systems in one SQL query
- Avoids costly migrations and keeps data under its existing governance
- Built on open-source Trino, with fast query performance reviewers praise
- Free plan and a $500-credit trial make evaluation cheap
Watch out for
- No published monthly price — paid pricing is pay-as-you-go and quote-led
- Narrower than full lakehouse platforms: it queries data but does not store or transform it
- Setup can be complex for teams new to federated querying

Dremio
Best for: Teams building an open lakehouse on Apache Iceberg that want fast self-service SQL
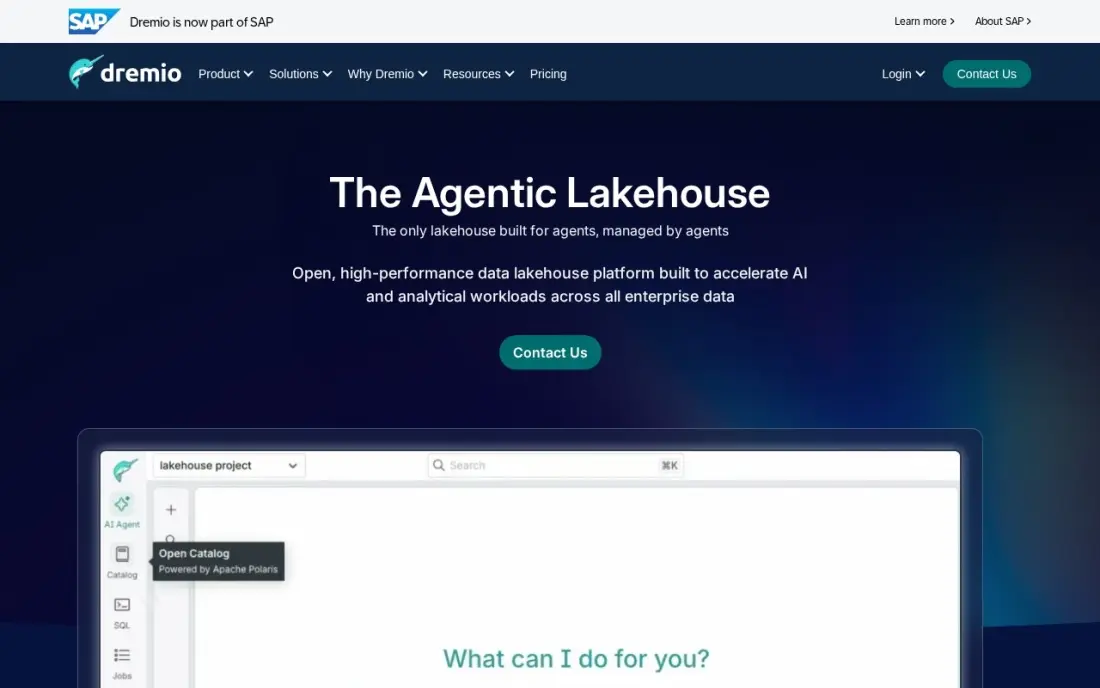
Dremio is built for the open lakehouse. Analysts run SQL directly on Apache Iceberg tables in object storage, a semantic layer defines shared metrics and permissions, and reflections speed up repeat queries automatically. Because the tables stay in an open format, other engines can read the same data.
Community Edition is free and self-managed. Dremio Cloud costs $0.20 per Dremio Compute Unit, so an XSmall engine runs $6.40 an hour, and a 30-day trial includes $400 in credits. The cloud service runs on AWS only, and the ecosystem is smaller than Databricks or Snowflake.
What we like
- Fast SQL directly on Apache Iceberg tables, with no ETL pipeline to build
- Semantic layer governs metrics and access for self-service analysts
- Reflections accelerate repeat queries automatically
- Free Community Edition and a $400-credit trial make it cheap to evaluate
Watch out for
- Cloud runs on AWS only, so Azure and Google Cloud teams take the self-managed path
- Smaller ecosystem than Databricks or Snowflake, with fewer integrations
- Community Edition omits enterprise security, governance and support
Cloudera
Best for: Regulated organisations that need one lake platform across on-premises and public cloud
Cloudera comes from the Hadoop world and still serves the organisations that grew up there. Cloudera Data Platform runs data engineering, warehousing, machine learning and streaming across public cloud, private cloud and on-premises, so a bank or hospital can keep regulated data in its own data centre while running other workloads in the cloud.
Public-cloud services bill per CCU-hour, from $0.04 for Data Hub to $0.17 for machine learning, and private cloud is an annual subscription per node. There is no free tier or trial, and reviewers mention cost and complexity more than for any other tool here. Choose it when data sovereignty is a requirement.
What we like
- One platform spans public cloud, private cloud and on-premises for hybrid estates
- Strong governance and security for regulated industries and data sovereignty
- Covers the full lifecycle: engineering, warehousing, machine learning and streaming
- Built on open source, with Spark and Airflow at the core
Watch out for
- No published prices and no free trial — budgeting starts with a sales conversation
- Reviewers cite high cost and complexity more than for any other tool here
- The Hadoop legacy lingers in perception, and setup takes longer than cloud-native rivals
The best data lake tools let you keep large volumes of raw data cheaply in object storage and still query it with the speed and governance of a warehouse. We compared eight platforms on open table formats, query engines, governance, cloud fit and how the bill is calculated, and every price below was checked on the vendor's own pricing page in November 2026.
How to choose the best data lake tools
- Start with your cloud. A lake lives in object storage, so the tool that works best with your existing AWS, Azure or Google Cloud account usually saves months of setup.
- Prefer open table formats. Delta Lake and Apache Iceberg let more than one engine read the same tables, which keeps you from being locked in to one vendor.
- Check governance before scale. Access control, lineage and data masking are hard to add later; make sure the catalog covers files, tables and models.
- Understand the billing unit. DBUs, credits, TiB scanned, RPU-hours and capacity units all behave differently; model one month of real queries before you sign.
- Match the tool to the skills you have. Spark and Python teams get more out of Databricks; SQL-only teams are faster on Snowflake, BigQuery or Dremio.
- Decide whether data must move. If it cannot, a federated engine such as Starburst queries it in place.
A lake is only useful once the data in it is trustworthy. Our data pipeline software guide covers the tools that load and clean data on the way in, and the big data analytics comparison looks at the same platforms from the analysis side.
Data lake tools pricing: what you will actually pay
Most of these tools charge for compute by usage and for storage separately, so there is no single monthly price to compare. A worked example helps. A team that scans 3 TiB of data a month in BigQuery pays nothing for the first 1 TiB and $6.25 for each TiB after, so $12.50 a month in query cost on demand. The same team running Redshift Serverless at the 4-RPU minimum for two hours a working day — about 44 hours a month — pays $1.50 an hour, or $66 a month, before storage.
Microsoft Fabric is the only flat price: F2 capacity costs $262.80 a month pay-as-you-go, or about $156.33 on a one-year reservation, so $3,153.60 a year versus about $1,876 reserved. Snowflake bills $2 per credit on Standard and $3 on Enterprise, so the same workload costs 50% more if you need one Enterprise feature. Databricks Jobs Compute starts at $0.15 per DBU, plus cloud servers on classic compute. Dremio Cloud's XSmall engine runs $6.40 an hour. Starburst and Cloudera are quote-led beyond their published unit rates.
Know the difference: data lake vs lakehouse
A plain data lake is object storage full of files — CSV, JSON, Parquet, logs, images — with a catalog that says where things are. It is cheap and flexible, but it has no transactions, so two jobs writing at once can corrupt a table, and analysts often struggle to find the trustworthy version.
A lakehouse keeps the same cheap storage but adds a table format such as Delta Lake or Iceberg, which brings transactions, schema enforcement, version history and fine-grained access control. That lets BI tools and SQL users work directly on lake data instead of copying it into a separate warehouse. Databricks, Dremio and Fabric are built around the lakehouse model, while Snowflake, BigQuery and Redshift approach the same goal from the warehouse side.
Quick comparison: tool type by need
| Buyer | Best pick | Why |
|---|---|---|
| Engineering and ML teams | Databricks | Full lakehouse with Unity Catalog, from $0.15/DBU |
| SQL-first analysts | Snowflake | No infrastructure to run, $2/credit on Standard |
| Google Cloud teams | Google BigQuery | Serverless with 1 TiB of queries free each month |
| AWS shops with data in S3 | Amazon Redshift | Queries S3 directly, Serverless from $1.50/hour |
| Microsoft shops | Microsoft Fabric | OneLake and Power BI on one capacity, from $262.80/month |
| Data that cannot move | Starburst | Federated SQL across lakes, warehouses and databases |
| Open Iceberg lakehouse | Dremio | Fast SQL on Iceberg, free Community Edition |
| Hybrid and regulated estates | Cloudera | One platform on-premises and in the cloud |
Mistakes to avoid
- Dumping data without a catalog. A lake with no ownership or documentation turns into a swamp that nobody trusts within a year.
- Leaving compute running. Idle clusters and warehouses are the most common source of surprise bills; set auto-stop on everything.
- Choosing a closed format by default. Storing tables in an open format keeps the option of changing engines later.
- Skipping partitioning. Unpartitioned tables force full scans, which is slow on every engine and expensive on scan-priced ones.
- Ignoring egress costs. Moving data between clouds or regions is billed by the cloud provider, not the lake tool, and adds up fast.
Related comparisons: Data Engineering Tools · Data Science Platforms · Customer Data Platforms · Embedded Analytics Tools for Data Analytics
How we chose
We shortlisted platforms that store or query data in cloud object storage at scale, then checked each vendor's pricing page in November 2026 and recorded the published unit rate, region and edition. Where pricing is quote-led, we say so rather than estimate. We compared open-format support, governance, cloud fit and the skills each tool expects. Ratings come from G2 pages checked on the dates shown in the sources. No vendor paid for a place in this list, and none of the links here are affiliate links.
What to do next
Pick the two tools that match your cloud and your team's skills, load one real dataset into each, and run the ten queries your analysts run most often. Compare speed and the cost report after a week. If you also want the data to feed better marketing decisions, book a free call with our team.
Frequently asked questions
What are the best data lake tools?
Databricks is the most complete lakehouse platform, Google BigQuery has the best free tier with 1 TiB of queries free every month, and Microsoft Fabric suits Microsoft shops with a flat capacity price from $262.80 a month. Starburst and Dremio are the picks for querying lake data where it already sits.
What is the difference between a data lake and a data warehouse?
A data lake stores raw files of any type cheaply in object storage and applies structure when you read them. A data warehouse stores cleaned, structured tables optimised for SQL. A lakehouse adds warehouse features such as transactions and governance on top of lake storage.
Is there a free data lake tool?
Yes. Google BigQuery gives 1 TiB of queries and 10 GiB of storage free each month, Databricks has a free edition for learning and small experiments, Dremio Community Edition is free and self-managed, and Starburst Galaxy has a free plan for exploring.
How much does a data lake cost?
Most tools charge for compute by usage and storage separately. Databricks Jobs Compute starts at $0.15 per DBU, Snowflake Standard at $2 per credit, BigQuery at $6.25 per TiB scanned and Redshift Serverless at $1.50 an hour. Microsoft Fabric's smallest capacity is $262.80 a month pay-as-you-go.
What is Apache Iceberg and why does it matter?
Iceberg is an open table format that adds transactions, schema changes and time travel to files in object storage. Because it is open, several engines can read the same tables, so you are less locked in to one vendor. Dremio is built around it.
Do small teams need a data lake?
Often not at first. If your data is mostly structured and under a few terabytes, a warehouse with a free tier such as BigQuery is simpler. A lake starts to pay off when you store large volumes of logs, files or events, or when machine learning needs raw data.
What is a data lake used for?
A data lake stores large volumes of raw data cheaply in object storage, such as logs, events, CSV, JSON, Parquet files and images, so it can be analysed later. Teams use it to feed SQL analytics, BI dashboards and machine learning that needs raw data. Tools like Databricks, Dremio and Amazon Redshift then query the files in place, without loading them into a separate system first.
What are the best data lakehouse tools?
Databricks is the fullest lakehouse: Delta tables add transactions and versioning to object storage, and Unity Catalog governs tables, files and models. Dremio is built for an open lakehouse on Apache Iceberg, with a free Community Edition. Microsoft Fabric puts a lakehouse, pipelines and Power BI on one capacity bill from $262.80 a month. Snowflake, BigQuery and Redshift reach the same goal from the warehouse side.
What are the alternatives to a data lake?
The main alternative is a data warehouse, which stores cleaned, structured tables for SQL; Snowflake, Google BigQuery and Amazon Redshift fit here, and BigQuery's free tier covers 1 TiB of queries a month. If your data cannot move, a federated engine such as Starburst queries lakes, warehouses and databases where they sit. For mostly structured data under a few terabytes, a warehouse is simpler than a lake.
Sources we checked (16)
- Databricks — www.databricks.com/pricing (checked November 6, 2026)
- Databricks reviews on G2 (checked November 6, 2026)
- Snowflake — www.snowflake.com/en/pricing (checked November 6, 2026)
- Snowflake reviews on G2 (checked November 6, 2026)
- Google BigQuery — cloud.google.com/bigquery/pricing (checked November 6, 2026)
- Google BigQuery reviews on G2 (checked November 6, 2026)
- Amazon Redshift — aws.amazon.com/redshift/pricing (checked November 6, 2026)
- Amazon Redshift reviews on G2 (checked November 6, 2026)
- Microsoft Fabric — azure.microsoft.com/en-us/pricing/details/microsoft-fabric (checked November 6, 2026)
- Microsoft Fabric reviews on G2 (checked November 6, 2026)
- Starburst — www.starburst.io/pricing (checked November 6, 2026)
- Starburst reviews on G2 (checked November 6, 2026)
- Dremio — www.dremio.com/pricing (checked November 6, 2026)
- Dremio reviews on G2 (checked November 6, 2026)
- Cloudera — www.cloudera.com (checked November 6, 2026)
- Cloudera reviews on G2 (checked November 6, 2026)
Make one of these tools?
We re-check this list every quarter. Send a correction, request a review, or ask about a clearly labeled sponsored spot.
Request a listingShamim
Founder of SerpAstra
A full-stack digital marketer and SEO strategist covering technical and local SEO, AI search visibility, paid ads and lead generation for local businesses, e-commerce brands and SaaS teams.
Free SEO and AI visibility audit
Find out what is holding your rankings back
Send us your site. Within 2 business days you get a written audit, an AI visibility check and a short fix list ranked by impact. Free, with no contract attached.
Request my free audit→Related buying guides
 Data, Analytics & AI10 Best Big Data Analytics Software in 2026, ComparedCompare the 10 best big data analytics software platforms on price, free tiers and AI features, with every price checked on November 6, 2026.Read guide →
 Data, Analytics & AI7 Best Data Pipeline Software Reviews in 2026, ComparedOur best data pipeline software reviews compare 7 tools on connectors, pricing model, free plans and who runs the servers, with prices checked on vendor pages.Read guide →
 Data, Analytics & AI12 Best Dashboard Software for Data Analytics in 2026, ComparedCompare the 12 best dashboard software for data analytics on price, free plans, AI features and refresh speed, with every price checked November 7, 2026.Read guide →